Portrait of Mengqi Huang

Mengqi Huang

黄梦琪
University of Science and Technology of China

My research interests include deep generative models, image/video/3D generation, and unified multimodal models. I am the recipient of the Best Student Paper Award at ACM Multimedia 2022 as the first author. In 2025, I was awarded the First Prize of the Natural Science Award from the China Society of Image and Graphics (CSIG) and the Special Prize of the President Scholarship of the Chinese Academy of Sciences (CAS). I have also received funding from the First National Natural Science Foundation of China for Youth Student Fundamental Research (Ph.D. student). I was selected for top industry talent programs including the Alibaba, ByteDance, etc.

研究方向为图像、视频、3D等视觉内容生成和多模态生成-理解统一模型。 博士期间以第一作者获CCF-A类国际会议ACM Multimedia 2022最佳学生论文奖。获2025年中国图像图形学会自然科学一等奖; 获批首届国家自然科学基金青年学生基础研究项目(博士研究生)。获2025年中国科学院院长特别奖。25年校招入选阿里星(校招P7)、字节跳动头部人才计划(校招3-1)等。

Career Timeline

  1. – Present

    Postdoctoral Researcher

  2. – Present

    Startup Journey

  3. –

    Researcher

    Image & Video Generation
    Intelligent Creation Department
  4. –

    Ph.D.

    Working with Prof. Zhendong Mao
  5. –

    B.Eng.

Funding

Selected Publications Google Scholar Profile

2026

Lance: Unified Multimodal Modeling by Multi-Task Synergy

Fengyi Fu*, Mengqi Huang*✉, Shaojin Wu*, Yunsheng Jiang*, Yufei Huo, Hao Li, Yinghang Song, Fei Ding, Jianzhu Guo✉, Qian He, Zheren Fu, Zhendong Mao, Yongdong Zhang
Technical Report

UFO: Chain-of-Evaluation for Omni-Condition Alignment in Multi-Modal Image Generation

Danning Zhang*, Yijing Lin*, Shuhan Zhuang*, Mengqi Huang✉, Shaojin Wu, Shancheng Fang, Zhendong Mao
ICML 2026

NativeTok: Native Visual Tokenization for Improved Image Generation

Bin Wu, Mengqi Huang✉, Weinan Jia, Zhendong Mao
ICASSP 2026 Oral

Unified Customized Generation by Disentangled Reward Modeling

Shaojin Wu, Mengqi Huang✉, Yufeng Cheng, Wenxu Wu, Jiahe Tian, Yiming Luo, Fei Ding, Qian He
CVPR 2026

Scaling Multi-Identity Consistency for Image Customization via Multi-to-Multi Matching Paradigm

Yufeng Cheng, Wenxu Wu, Shaojin Wu, Mengqi Huang✉, Fei Ding, Qian He
CVPR 2026

MoGA: Mixture-of-Groups Attention for End-to-End Long Video Generation

Weinan Jia, Yuning Lu✉, Mengqi Huang✉, Hualiang Wang, Binyuan Huang, Nan Chen, Mu Liu, Jidong Jiang, Zhendong Mao
ICLR 2026

Towards Accurate Image Generation via Dynamic Generative Image Transformer

Zhendong Mao, Mengqi Huang, Yijing Lin, Quan Wang, Lei Zhang, Yongdong Zhang
IEEE TPAMI 2026

RealCustom++: Representing Images as Real Textual Word for Real-Time Customization

Zhendong Mao, Mengqi Huang, Fei Ding, Mingcong Liu, Qian He, Yongdong Zhang
IEEE TPAMI 2026

LayerEdit: Disentangled Multi-Object Editing via Conflict-Aware Multi-Layer Learning

Fengyi Fu, Mengqi Huang✉, Lei Zhang, Zhendong Mao
AAAI 2026

2025

Pro3D-Editor: A Progressive-Views Perspective for Consistent and Precise 3D Editing

Yang Zheng, Mengqi Huang✉, Nan Chen, Zhendong Mao
NeurIPS 2025

Less-to-More Generalization: Unlocking More Controllability by In-Context Generation

Shaojin Wu, Mengqi Huang✉, Wenxu Wu, Yufeng Cheng, Fei Ding, Qian He
ICCV 2025

LongAnimation: Long Animation Generation with Dynamic Global-Local Memory

Nan Chen, Mengqi Huang, Yihao Meng, Zhendong Mao
ICCV 2025

A4A: Adapter for Adapter Transfer via All-for-All Mapping for Cross-Architecture Models

Keyu Tu, Mengqi Huang, Zhuowei Chen, Zhendong Mao
CVPR 2025

D^2iT: Dynamic Diffusion Transformer for Accurate Image Generation

Weinan Jia, Mengqi Huang, Nan Chen, Lei Zhang, Zhendong Mao
CVPR 2025

Dragin3D: Image Editing by Dragging in 3D Space

Weiran Guang, Xiaoguang Gu, Mengqi Huang, Zhendong Mao
CVPR 2025

FeedEdit: Text-Based Image Editing with Dynamic Feedback Regulation

Fengyi Fu, Lei Zhang, Mengqi Huang, Zhendong Mao
CVPR 2025

CustomContrast: A Multilevel Contrastive Perspective For Subject-Driven Text-to-Image Customization

Nan Chen, Mengqi Huang, Zhuowei Chen, Yang Zheng, Lei Zhang, Zhendong Mao
AAAI 2025

2024

RealCustom: Narrowing Real Text Word for Real-Time Open-Domain Text-to-Image Customization

Mengqi Huang, Zhendong Mao, Mingcong Liu, Qian He, Yongdong Zhang
CVPR 2024

Gradual Residuals Alignment: A Dual-Stream Framework for GAN Inversion and Image Attribute Editing

Hao Li, Mengqi Huang, Lei Zhang, Bo Hu, Yi Liu, Zhendong Mao
AAAI 2024

DreamIdentity: Improved Editability for Efficient Face-identity Preserved Image Generation

Zhuowei Chen, Shancheng Fang, Wei Liu, Qian He, Mengqi Huang, Yongdong Zhang, Zhendong Mao
AAAI 2024

2023 & 2022

Towards Accurate Image Coding: Improved Autoregressive Image Generation With Dynamic Vector Quantization

Mengqi Huang, Zhendong Mao, Zhuowei Chen, Yongdong Zhang
CVPR 2023 Highlight, 2.5% of submitted papers

DSE-GAN: Dynamic Semantic Evolution Generative Adversarial Network for Text-to-Image Generation

Mengqi Huang, Zhendong Mao, Penghui Wang, Quan Wang, Yongdong Zhang
ACM Multimedia 2022 Best Student Paper Award, 1/3009 of submitted papers

* Equal contribution. ✉ Corresponding author.

Awards & Honors

2025
CSIG Natural Science Award — First Prize
中国图像图形学会自然科学一等奖 · 《内生知识驱动的图像-文本语义关联》
CAS President Scholarship — Special Prize
中国科学院院长特别奖
Industry Recognition
25年校招入选阿里星(校招P7)、字节跳动头部人才计划(校招3-1)
2022
Best Student Paper Award
ACM Multimedia 2022 · First author · CCF-A

Industrial Research Experience

Intelligent Creation Department · July 2023 – July 2026
Wonderful 3 years at ByteDance
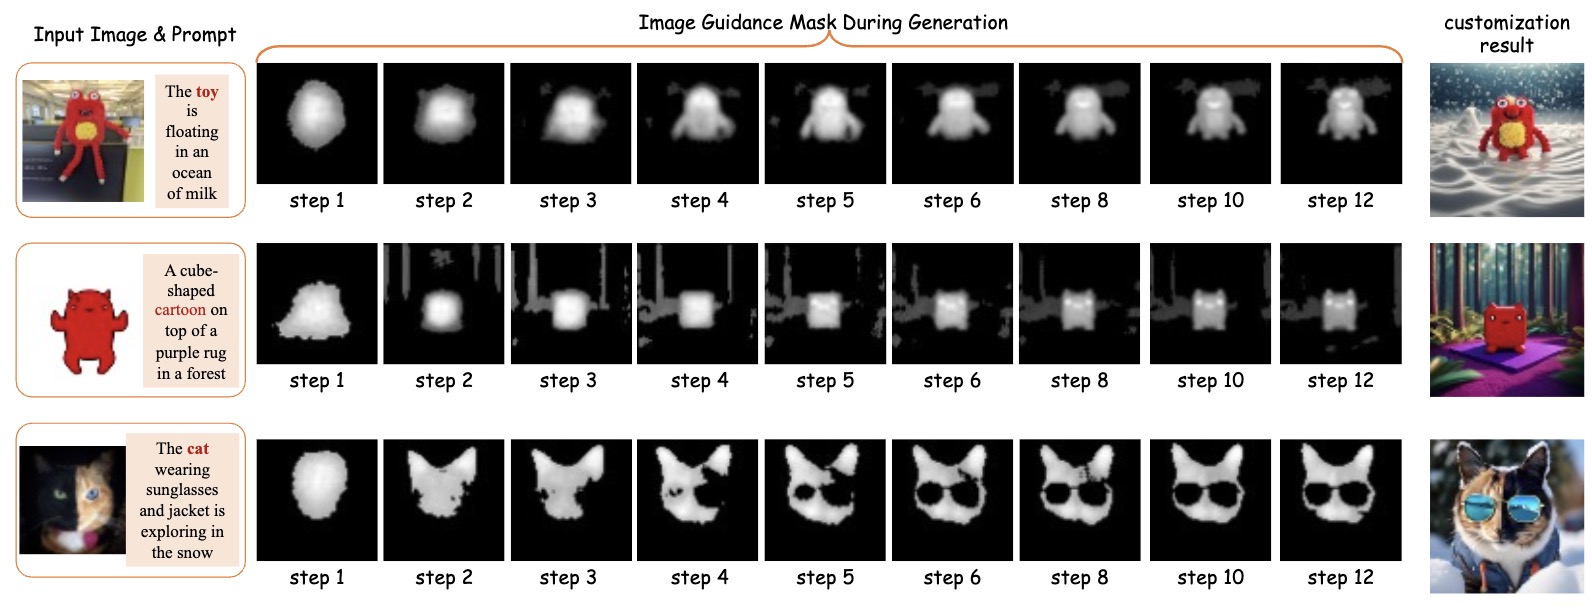
Examples of subject-driven image generation with RealCustom

RealCustom: Narrowing Real Text Word for Real-Time Open-Domain Text-to-Image Customization

Mengqi Huang, Zhendong Mao, Mingcong Liu, Qian He, Yongdong Zhang
CVPR 2024 & IEEE TPAMI 2026
RealCustom enables subject-driven image generation while preserving text-based control. It represents reference subjects as real textual words to jointly optimize subject fidelity and prompt alignment.
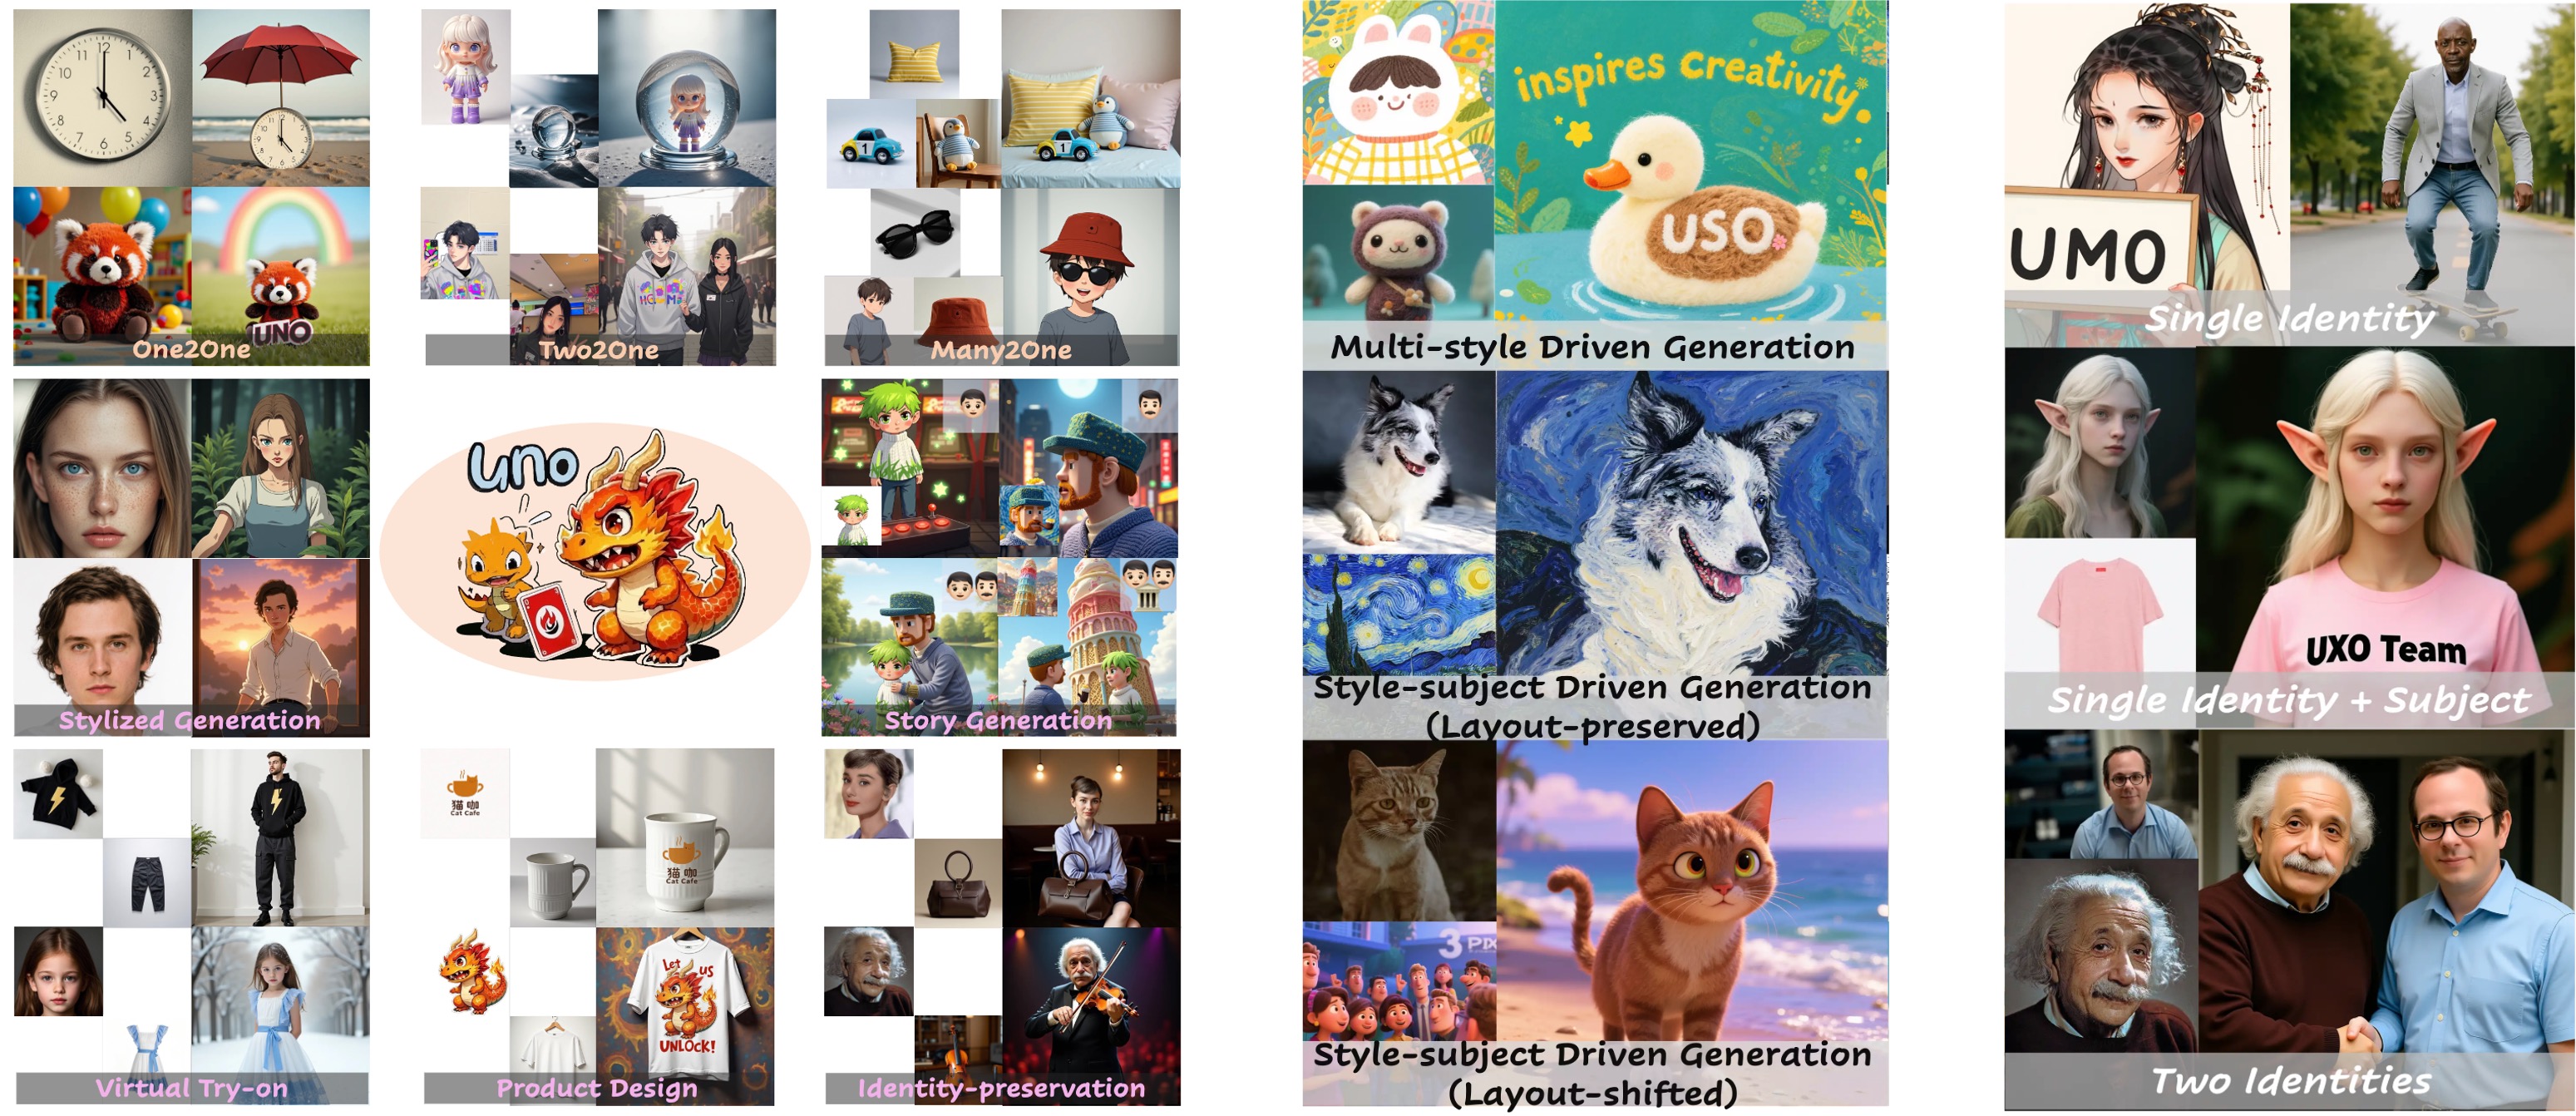
Overview of the UXO series for image customization

UXO Series Research

The UXO series studies subject- and style-conditioned image generation, including controllability, disentangled reward modeling, and multi-identity consistency.
  • UNO project logo
    UNO: Less-to-More Generalization: Unlocking More Controllability by In-Context Generation
    Shaojin Wu, Mengqi Huang✉, Wenxu Wu, Yufeng Cheng, Fei Ding, Qian He
    ICCV 2025
  • USO project logo
    USO: Unified Customized Generation by Disentangled Reward Modeling
    Shaojin Wu, Mengqi Huang✉, Yufeng Cheng, Wenxu Wu, Jiahe Tian, Yiming Luo, Fei Ding, Qian He
    CVPR 2026
  • UMO project logo
    UMO: Scaling Multi-Identity Consistency for Image Customization via Multi-to-Multi Matching Paradigm
    Yufeng Cheng, Wenxu Wu, Shaojin Wu, Mengqi Huang✉, Fei Ding, Qian He
    CVPR 2026
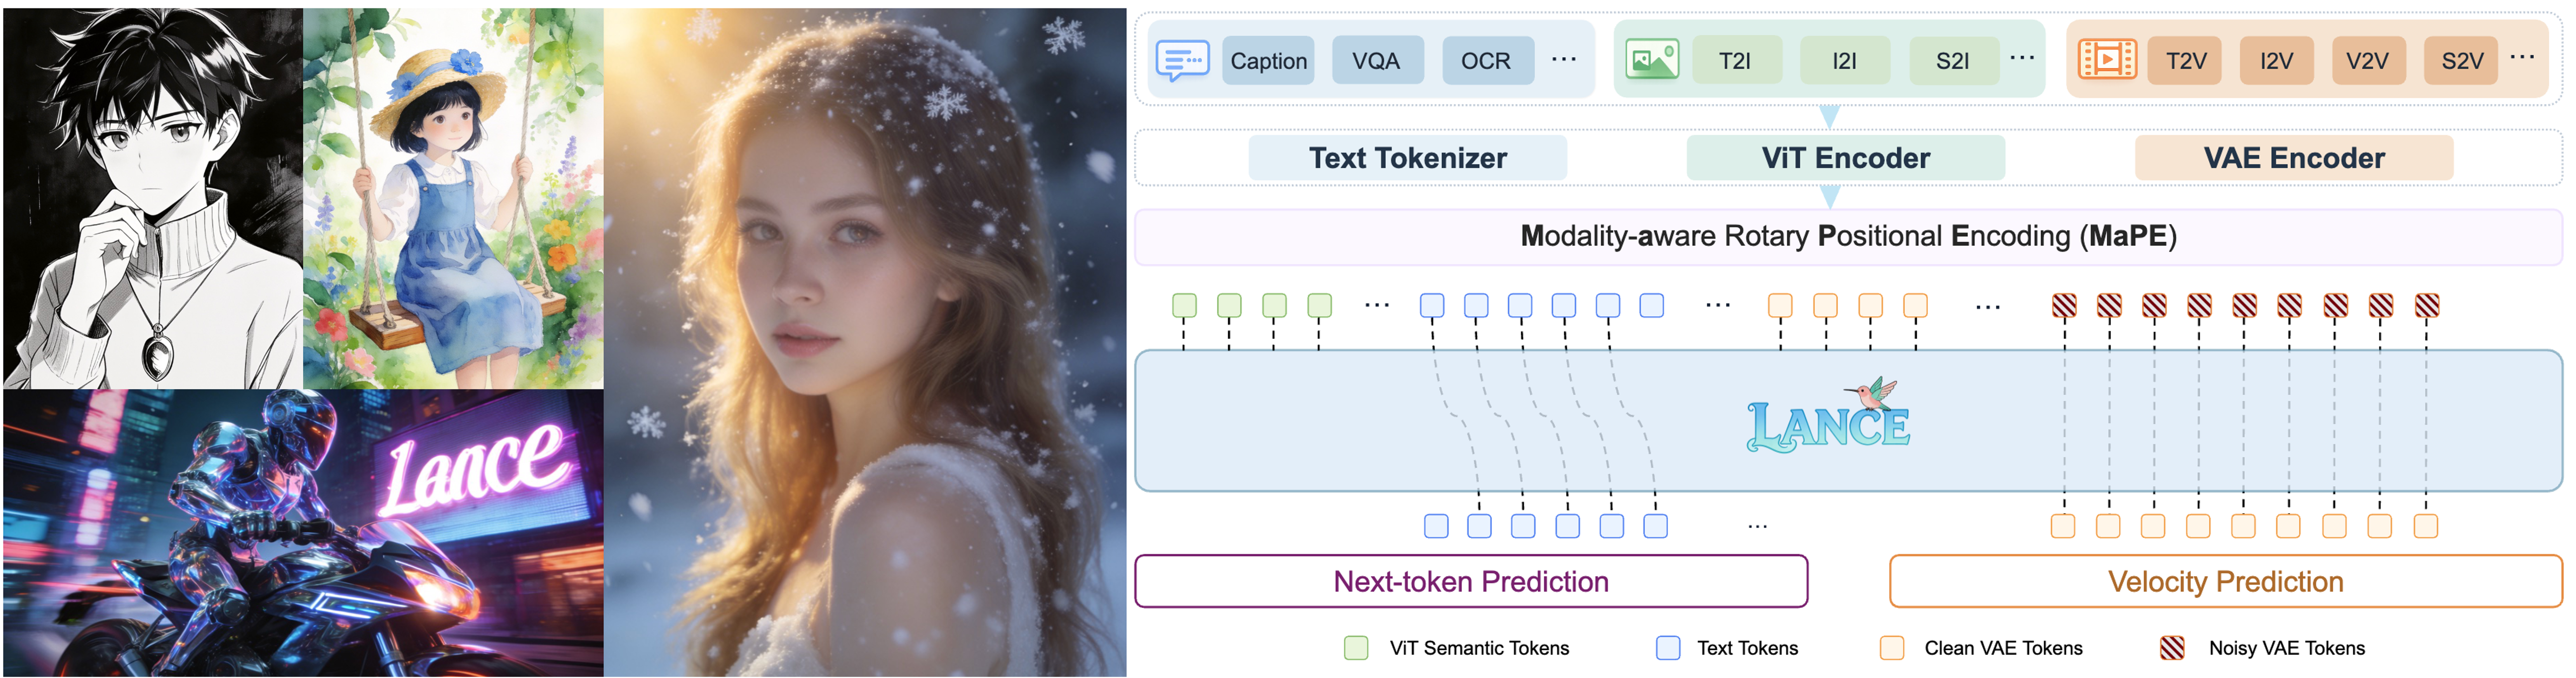
Overview of Lance for unified multimodal understanding and generation

Lance: Unified Multimodal Modeling by Multi-Task Synergy

Fengyi Fu*, Mengqi Huang*✉, Shaojin Wu*, Yunsheng Jiang*, Yufei Huo, Hao Li, Yinghang Song, Fei Ding, Jianzhu Guo✉, Qian He, Zheren Fu, Zhendong Mao, Yongdong Zhang
Technical Report
Lance is a 3B unified multimodal model for image and video understanding, generation, and editing.
Last updated: